RAG explained
What is RAG?
Retrieval-Augmented Generation (RAG) connects a language model to external knowledge sources. Relevant content is retrieved at runtime and supplied as context for the answer.
RAG in one sentence
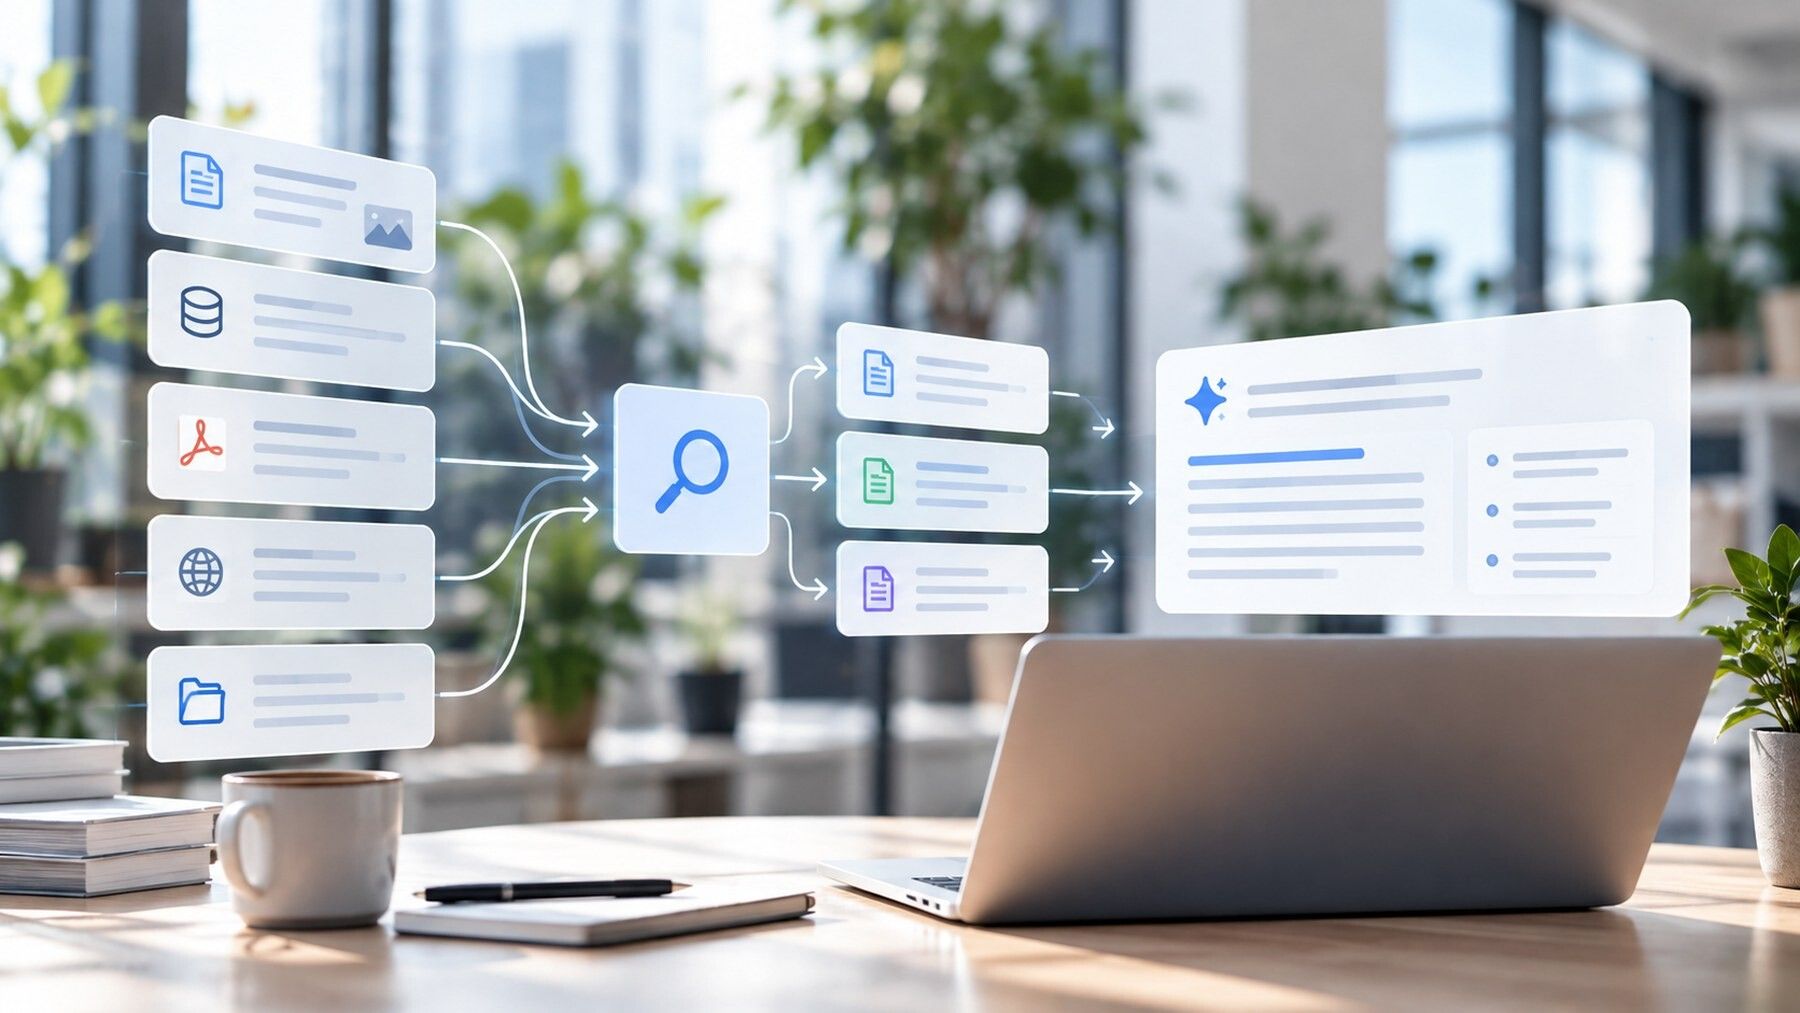
RAG adds a retrieval step before the language model: the system finds relevant content in defined sources and sends those passages to the model together with the user’s question.
How does RAG work?
A typical RAG system has several stages. Documents and other content are first structured, split into useful sections and prepared for search. When a user asks a question, the system retrieves relevant passages. Those passages are then supplied to the language model together with the question.
- Prepare sources: ingest documents, metadata and permissions.
- Make content searchable: prepare full-text, vector or hybrid retrieval.
- Retrieve relevant passages: select and filter results for the specific question.
- Generate an answer: provide the model with the question plus selected source material.
- Evaluate the result: measure source grounding, completeness and subject-matter quality.
Why not put every document into the prompt?
That can work for very small collections. In real company knowledge bases it quickly becomes expensive, slow and difficult to manage. RAG aims to select the content relevant to a specific question rather than sending every document on every request.
When is RAG useful?
- Answers should be based on internal documents, policies or product knowledge.
- Sources are updated regularly.
- Supporting passages should be visible and traceable.
- Permissions or tenant separation need to be enforced.
- A general-purpose language model does not reliably know the required information.
What are the limitations?
RAG does not guarantee a correct answer. Errors can occur during document processing, retrieval or source selection, and the model can still misinterpret supplied context. Retrieval quality, source grounding and answer quality should therefore be tested separately.
RAG is more than a vector database
A robust system needs appropriate document processing, metadata, permissions, search logic, evaluation and monitoring. The vector database is only one part of the architecture. In some cases, full-text search or a hybrid approach is more suitable.
Questions to clarify before a RAG project
- Which sources are authoritative?
- How current and structured is the data?
- Which users may access which content?
- Do answers always need to cite sources?
- What does a representative evaluation dataset look like?
- How should contradictory or outdated documents be handled?
Primary source
The term Retrieval-Augmented Generation was introduced in the 2020 paper “Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks” by Patrick Lewis and co-authors. Modern enterprise RAG systems often go substantially beyond that research architecture in their ingestion, access control, evaluation and operational design.