RAG system development

RAG systems that make company knowledge searchable and useful.

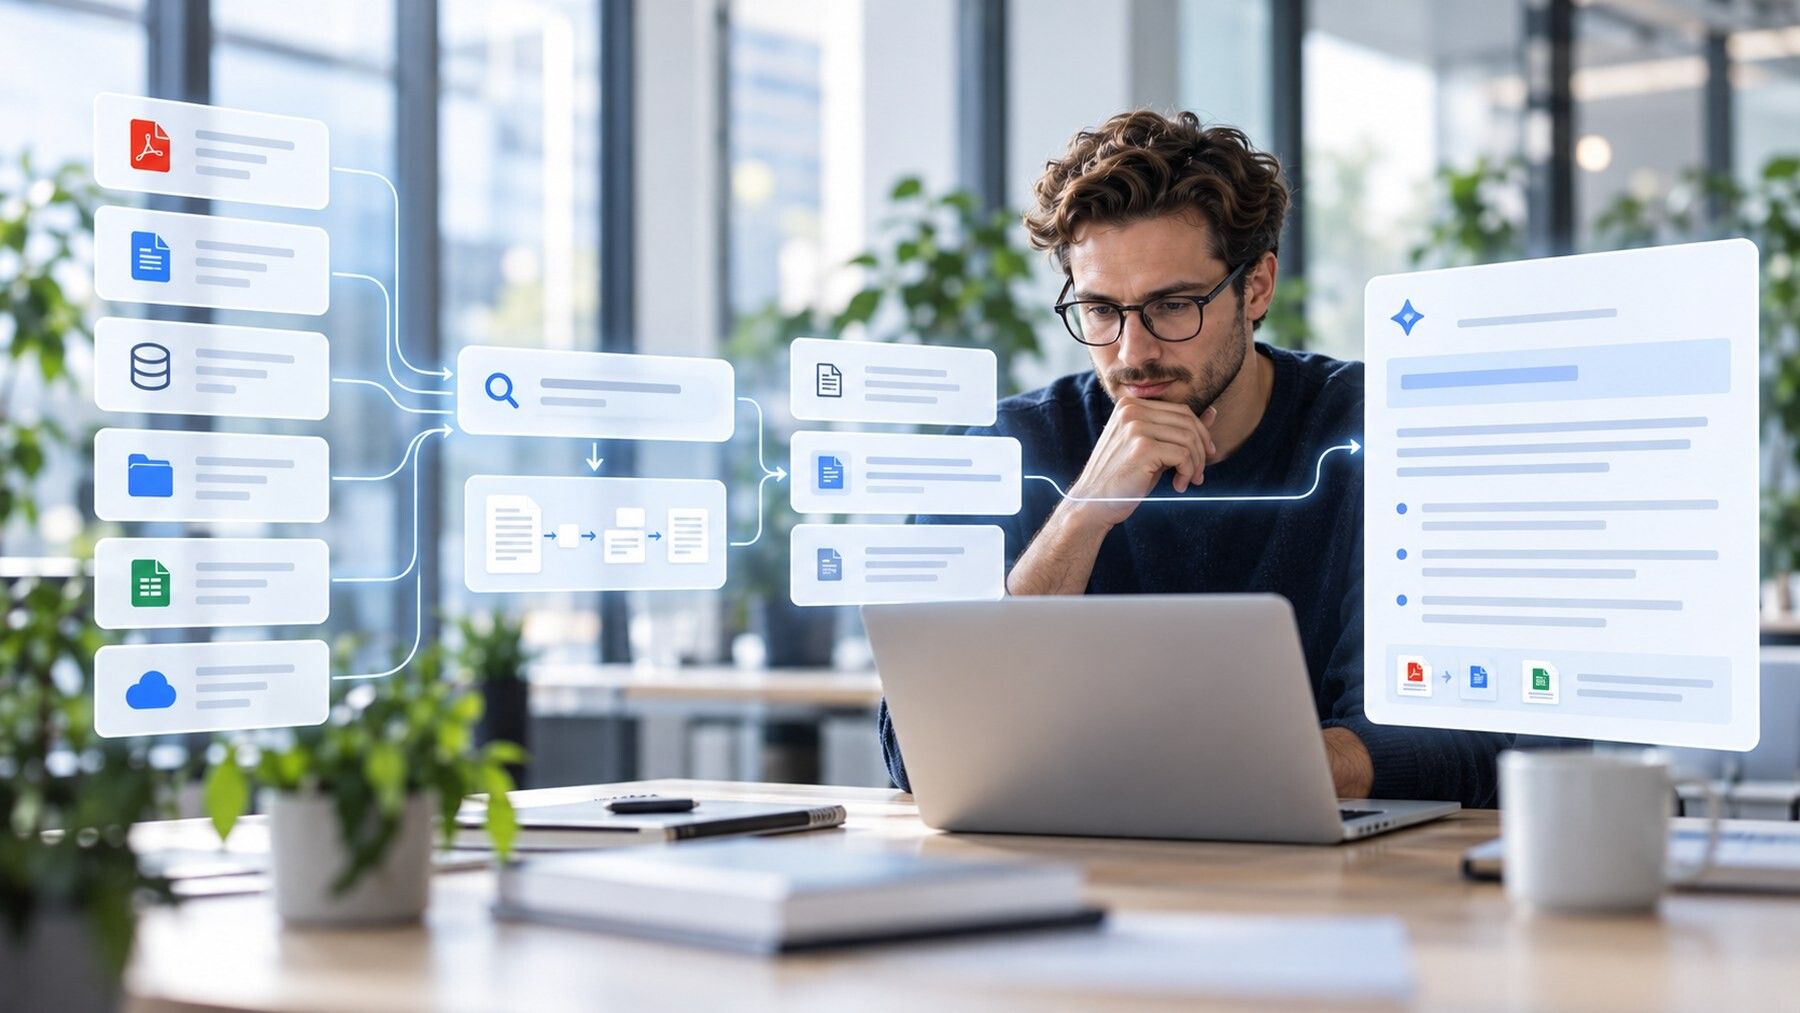
Retrieval-Augmented Generation connects a language model to your own knowledge sources. Relevant content is retrieved at runtime and supplied as context, rather than retraining a model on every company document.

Documents and data sources prepared for a knowledge-grounded answer
Strategic guidance before implementation
Custom solution instead of a standard tool
Secure integration into your system landscape
Operation and continuous development considered from the start

Typical starting points

When this service is a good fit

  • Knowledge is fragmented across documents, wikis and business systems
  • Employees spend too long searching for reliable information
  • Answers need to be grounded in your own sources
  • Sources and supporting passages need to remain traceable

Scope

What we deliver

  • Source and data analysis
  • Document processing, chunking, embeddings and retrieval
  • Permissions and tenant separation
  • Evaluation of retrieval, answer quality and source grounding

Use cases

Where RAG Systems can create concrete value.

The right architecture depends on the process, data, existing systems and the cost of a wrong decision. These examples are common use cases, not blanket recommendations.

01

Internal knowledge search

02

Policy and handbook assistants

03

Support based on product and service documentation

04

Research across large document collections

05

Specialist portals with source references

06

Multi-tenant knowledge systems

Decision criteria

When the approach fits – and when it does not.

We first assess whether AI genuinely adds value compared with conventional software, search or workflow automation for the specific task.

Questions we clarify early

  • How current and structured are the sources?
  • Do answers need to cite sources?
  • Are there permission or tenant boundaries?
  • How will answer quality be reviewed by subject-matter experts?

Quality and control

AI capabilities need measurable quality criteria.

Non-deterministic outputs should not be judged from a handful of impressive demos. We define representative test cases, observe failure patterns and design fallbacks or human approvals where the business context requires them.

  1. Measure retrieval and answer quality separately
  2. Carry source metadata and freshness through the pipeline
  3. Apply permissions before retrieval
  4. Use test sets with real questions and expected sources

How we work

From business problem to robust solution.

We do not start with a model name. We start with the process, users, available data and technical constraints. From there, we design an architecture that balances business value, privacy, cost, maintainability and operations.

Analysis and target architecture

At the start, we clarify the current situation, users, data sources, integrations and quality requirements. If core assumptions are still open, we shape an initial phase specifically to test those assumptions.

Development and integration

The software is developed iteratively against real data and interfaces. Critical integrations and AI capabilities are tested early so technical risks become visible before the end of the project.

Operation and continuous improvement

For production systems, monitoring, cost control, logging, failure paths and model or provider changes are part of the architecture. An AI project does not end with an impressive demo.
Frequently asked questions

Key questions about RAG Systems.

Direct answers to points that should be clarified before making a technical decision.

What is RAG in simple terms?

RAG first retrieves relevant information from defined sources and then provides that material to a language model as context. This lets answers draw on current, company-specific knowledge.

Does every RAG system need a vector database?

No. Vector search is often useful, but it is not the only retrieval method. Depending on the data, full-text search, filters, hybrid retrieval or structured queries may be more important.

Does RAG prevent hallucinations?

No. RAG can improve grounding, but it does not guarantee correct answers. Retrieval, prompting, source grounding and answer quality must be evaluated separately.

Can you build a RAG system using our own documents?

Yes. PDFs, manuals, wikis, databases and other knowledge sources can be connected when ingestion, updates, metadata and permissions are defined properly.

Can a RAG system include source citations and access controls?

Yes. Retrieved passages and metadata can be retained and shown with answers. Access controls should be enforced before retrieval so users only receive content they are authorised to see.

Let’s turn your AI idea into a concrete software project.

In an initial conversation, we clarify the objective, current situation and sensible next steps.

To get started, your objective, existing systems and the main open question are enough.